Find Minimum Depth of Binary Tree
Difficulty: Easy, Asked-in: Facebook, Amazon.
Key takeaway: An excellent problem to learn problem-solving using recursive and iterative traversals. This is also a question to understand problem solving using BFS when solution is nearest to the root node.
Let's understand the problem!
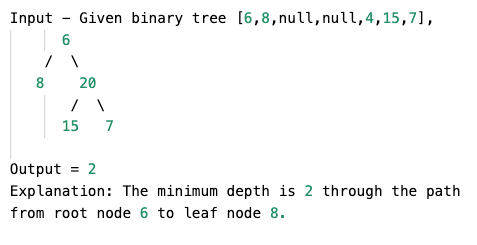
Given a binary tree, find its minimum depth. The minimum depth is the number of nodes along the shortest path from the root node down to the nearest leaf node. The path has to end on a leaf node.
Example
Discussed solution approaches
- Using depth-first Search: Recursive tree traversal
- Using breadth-first search: Iterative tree traversal
Using depth-first search: Recursive traversal
Solution idea and steps
We can find the solution by solving two subproblems: finding the min depth of the left subtree and finding the min depth of the right subtree. Here is an idea: If we know the min depth of both the left and right subtrees, then the min depth of the tree = 1 + min (min depth of the left subtree, min depth of the right subtree).
- Suppose treeMinDepth(root) will return the value of the min-depth of the tree.
- if(root == NULL), return 0. This is the base case.
- if(root->left == NULL): we recursively call the same function for the right subtree. In other words, there is no left sub-tree, so min depth of the tree = 1 + min depth of the right subtree. treeMinDepth(root) = 1 + treeMinDepth(root->right).
- if(root->right == NULL): we recursively call the same function for the left subtree. There is no right sub-tree, so min depth of the tree = 1 + min depth of the left subtree. treeMinDepth(root) = 1 + treeMinDepth(root->left).
- If both children are not NULL: we recursively call the same function for the left and right subtree, calculate the min-depth and get minimum of both to calculate the min-depth of the tree. treeMinDepth(root) = 1 + min (treeMinDepth(root->left), treeMinDepth(root->right)).
Solution pseudocode
treeMinDepth(root)
    if root is null
        return 0

    if root.left is null
        return 1 + treeMinDepth(root.right)

    if root.right is null
        return 1 + treeMinDepth(root.left)

    return 1 + min(treeMinDepth(root.left), treeMinDepth(root.right))
Time and space complexity analysis
We are traversing each node of the tree only once. Time complexity = O(n).
Space complexity = O(h) for recursion call stack. Space complexity is equal to the maximum depth of the recursion tree which is equal to the height of the tree (h), where O(log n) < h < O(n).
Using breadth-first search: Iterative traversal
Solution idea
Now, critical questions are: Can we solve this problem iteratively using BFS traversal? How do we calculate the minimum depth using this idea? Is there some hidden information in the problem that could help us solve it efficiently? Let's think!
Here is an observation: The node with the minimum depth will always be the first leaf node if we traverse the tree level by level. In other words, when traversing the tree level by level, we only need to return the depth of the first encountered leaf node.
In a practical scenario, this idea would be much more efficient compared to the DFS approach because, in the DFS approach, we may end up traversing the entire tree even when the topmost leaf is close to the root. But in BFS traversal, we can access the nodes from top to bottom in level order, which will help us quickly find the topmost leaf node in fewer steps.
For example, suppose we have a tree where the left subtree has a depth of 100 and the right subtree has a depth of 1. With DFS, we would first traverse all the 100 nodes in the left subtree before finally reaching the right subtree with a depth of 1 and identifying it as the minimum depth. With BFS, instead of traversing 101 nodes to determine the minimum depth, we can obtain the value in just two steps. Now, imagine the difference in efficiency when dealing with thousands of nodes in the left subtree!
Solution steps
- If the tree is empty, return 0.
- We enqueue the root in a queue with depth 1.
- Now repeatedly remove the front node from the queue. If it is a leaf (no children), then it is the first leaf node, which will give the minimum depth. So we return its depth. Otherwise, we add each existing child to the queue with a depth one greater than its parent’s.
Solution pseudocode
treeMinDepth(root)
    if root is null
        return 0

    queue = empty queue
    enqueue (root, 1)

    // Level-order traversal visits nodes increasing depth
    while queue is not empty
        (node, depth) = front of queue
        dequeue queue
        // The first leaf reached is the nearest leaf
        if node.left is null and node.right is null
            return depth

        // Add existing children to the queue with their depth
        if node.left is not null
            enqueue (node.left, depth + 1)

        if node.right is not null
            enqueue (node.right, depth + 1)

    return 0
Time and space complexity analysis
In the worst case, total number of queue operations = 2n, because each node gets inserted and deleted only once in BFS traversal. So time complexity = O(n), where n is the total number of nodes. Space complexity = O(w) because BFS traversal requires queue size proportional to the max-width of the tree (w).
Critical ideas to think!
- Why do we need a queue data structure in the level-order traversal?
- What is the worst-case and best-case space complexity in the BFS approach?
- Can we solve this problem using all DFS traversals?
- Why do we prefer BFS when the solution node is closer to the root? In which scenario do we prefer the DFS approach?
- Can we implement the BFS approach without using a tuple or pair?
Suggested coding problems to practice
- Max depth of the binary tree
- Find the diameter of a binary tree
- Count all leaf nodes in a binary tree
- Root to leaf paths with the sum
- Count all nodes with one child
- Depth of the deepest odd level node
Enjoy learning, Enjoy coding, Enjoy problem-solving!