Difficulty: Medium, Asked-in: Google, Amazon, Microsoft, Goldman Sachs, Nvidia.
Key takeaway: An excellent problem to learn problem-solving using fast and slow pointers (Floyd's cycle detection algorithm). We can solve several questions using the similar idea.
Let’s understand the problem
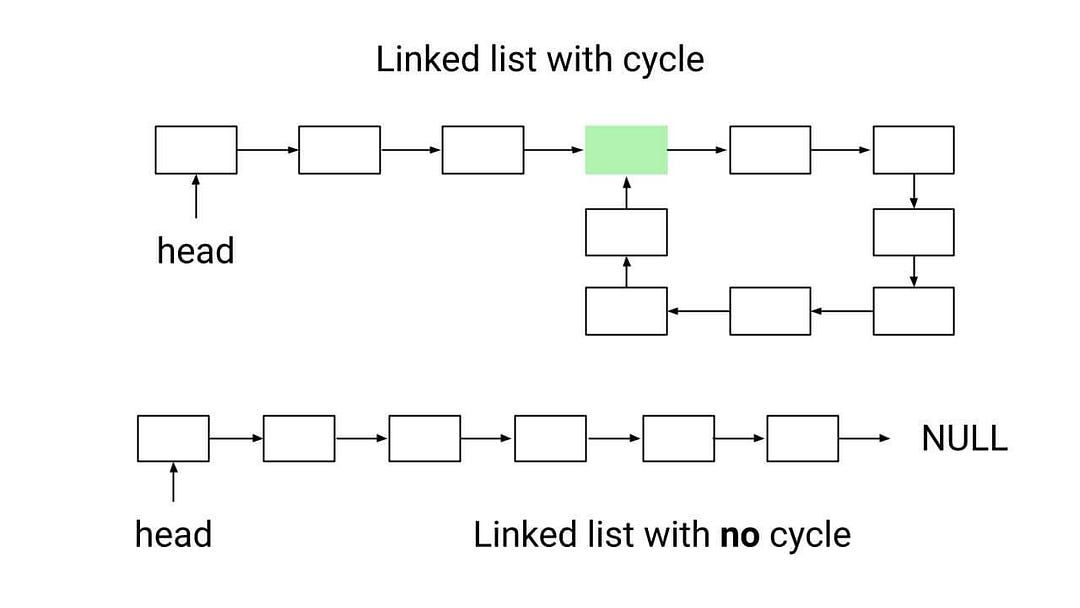
Given the head of a linked list, write a program to find if linked list has a cycle or not. Return true if there is a cycle, otherwise, return false.
Critical note related to the problem
In a singly linked list, we are usually given a reference to the first node to perform various operations like traversal, searching, insertion, deletion, merging, etc. These operations require a list without loops or cycles.
When a linked list has a cycle, there is no "end" node, and one of the nodes is the next node of two different nodes. This means that when we iterate through the list, we will encounter the nodes in the cycle multiple times, and iteration will fail. To avoid this, it is important to detect linked lists with cycles before applying an iterative approach.
Discussed solution approaches
- Brute force approach using hash table
- Using boolean flag inside linked list node
- Efficient approach using fast and slow pointers
Brute force approach using hash table
Solution idea
The basic idea is to traverse the linked list and use a hash table to keep track of the nodes that have been visited during the traversal. If we encounter a node that has already been visited, it means that there is a cycle in the linked list because this node must be part of a cycle. If we reach the end of the list without encountering any visited nodes again, it means there is no cycle.
Solution pseudocode
detectLinkedListLoop(head)
    H = empty hash map
    currNode = head

    while currNode != NULL
        if currNode exists in H
            return true

        H[currNode] = true
        currNode = currNode -> next

    return false
Time and space complexity analysis
For each node, we perform one insert operation and one search operation. So the time complexity = O(n). Space complexity = O(n) because we use a hash table to store the nodes of the linked list.
Using boolean flag inside linked list node
Solution idea
Can we optimise the above approach by avoiding the overhead of hash table operations? One way to do this is to add a visited flag to the linked list node structure. This flag helps us keep track of the nodes that have already been visited and detect when a node is encountered more than once during traversal.
To implement this approach, we traverse the linked list and set the visited flag to 1 whenever we visit a node for the first time. If we encounter a node whose visited flag is already set to 1, it means that the linked list contains a cycle. Note: visited flag must be initialised to 0 for every node before starting the traversal.
Solution pseudocode
detectLinkedListLoop(head)
    curr = head

    while curr != NULL
        if curr -> visited == 1
            return true

        curr -> visited = 1
        curr = curr -> next

    return false
Time and space complexity analysis
Time complexity = O(n), because we traverse each node in the list once. But still it has a space complexity of O(n) because it uses an extra variable (visited flag) for each node.
Using fast and slow pointers (Floyd's cycle detection algorithm)
Solution idea
The above solutions use O(n) space, so the critical question is: Can we optimise further and detect a cycle in a linked list using O(n) time and O(1) space?
This idea of cycle detection is based on an algorithm known as Floyd's Cycle-Finding Algorithm, also called the Tortoise and the Hare Algorithm. It uses two pointers: a slow pointer and a fast pointer, which move through the list at different speeds. At each iteration, the slow pointer moves one step, while the fast pointer moves two steps. If the two pointers ever meet, it means that the linked list contains a cycle.
Solution steps
- We initialize two pointers, fast and slow, with the head of the linked list.
- Now we run a loop to traverse the linked list. At each step, move the slow pointer to one position and the fast pointer to two positions.
- If the fast pointer reaches the end of the list (i.e., fast == NULL or fast->next == NULL), there is no loop in the linked list. Otherwise, the fast and slow pointers will eventually meet at some point, which means there is a loop in the linked list.
The critical question is: Why does this happen? The basic intuition is simple: If there is a cycle, the fast pointer will eventually catch up with the slow pointer because it moves faster. This is similar to two people running at different speeds on a circular track: eventually, the faster person will catch up with the slower person.
Solution pseudocode
detectLinkedListLoop(head)
    slow = head
    fast = head

    while fast != NULL AND fast -> next != NULL
        slow = slow -> next
        fast = fast -> next -> next

        if slow == fast
            return true

    return false
Some critical observations
In Floyd's cycle finding algorithm, the fast pointer moves at twice the speed of the slow pointer. This means that the gap between the two pointers increases by one after each iteration. For example, after the fifth iteration, the fast pointer will have moved 10 steps and the slow pointer will have moved 5 steps (the final gap is 5 steps).
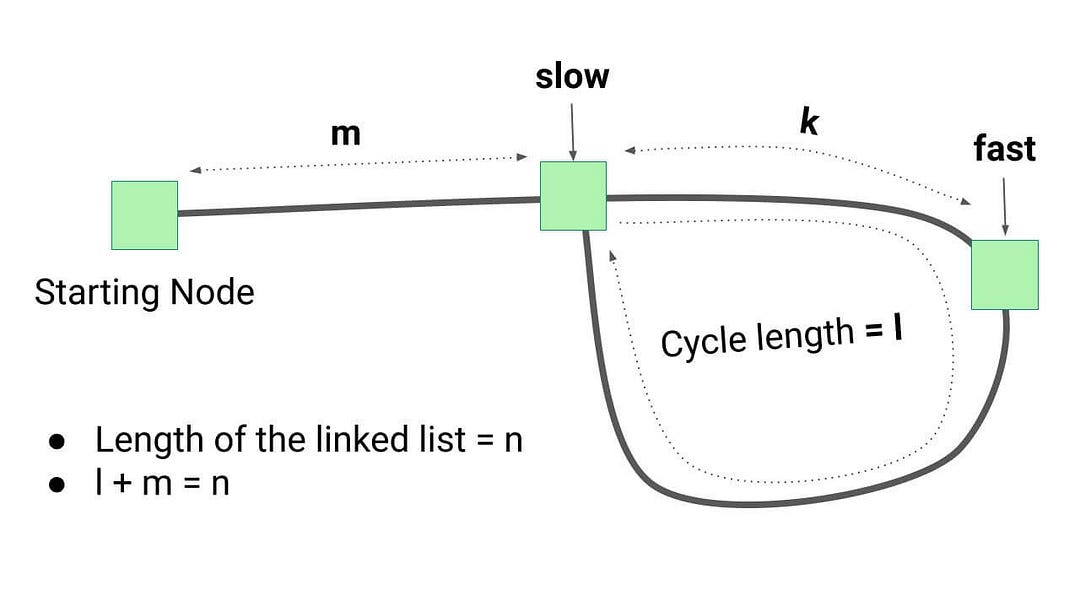
When the slow pointer enters the loop, the fast pointer is already inside the loop. Suppose at this point, the fast pointer is at distance k (k < l, where l is the length of the loop) from the slow pointer. As the two pointers move through the loop, the gap between them increases by 1 after each iteration. When the gap becomes equal to the length of the loop (l), the pointers will meet because they are moving in a cycle of length l. The total number of steps traveled by both pointers in the cycle before they meet at a common point is l - k.
Time and space complexity analysis
Suppose:
- Total number of nodes in linked list = n.
- The length of linked list cycle (if any) = l.
- The distance of the cycle's starting point from beginning = m. Here l + m = n.
- When slow pointer enters the loop, fast pointer distance from the slow pointer = k.
Case 1: When there is no loop in linked list.
Fast pointer will reach the end after n/2 steps. So, Time complexity = O(n).
Case 2: When there is a loop in linked list.
Both pointers will move m steps before slow pointer take entry into the loop. Inside the loop, both pointers will travel (l - k) steps before meeting at some common point. Time complexity = Total number of steps traveled by both pointers from start to meeting at common point = m + (l - k) = l + m - k = n - k (equation 1).
If slow pointer travel m distance from start to reach the bridge point, then fast pointer will travel 2m distance from the start. There will be two cases:
When m < l: k = m and total steps travelled by both pointers before meeting at a common point = n - k = n - m (From equation 1). So time complexity in the worst case = O(n), where the worst-case scenario occurs when m = 1.
When m >= l: In this situation, fast pointers will first move m distance to reach the bridge point and revolve m/l times in the cycle. So the distance of fast pointer from the bridge point (k) = m mod l.
Total no of steps travelled by both pointers before meeting at the common point = n - k = n - m mod l (From equation 1). So time complexity in the worst case = O(n), where worst-case scenario occurs when m = l.
Overall, time complexity would be O(n) in the worst case.
Critical ideas to think!
- How do we modify the above approaches to remove the loop?
- Design an algorithm to find the loop length in the linked list.
- If there is a loop in the linked list, what would be the best-case of the fast and slow pointer approach?
- How do we find the bridge node if there is any loop present?
- Can we solve this problem using some other approach?
- Is it necessary to move the fast pointer with double speed? What will happen if we move the fast pointer with speed four times the slow pointer?
Comparison of time and space complexities
- Using hash table: Time = O(n), Space = O(n)
- Using linked list augmentation: Time = O(n), Space = O(n)
- Floyd’s cycle detection algorithm: Time = O(n), Space = O(1)
Suggested problems to practice
- Remove loop from the linked list
- Return the node where the cycle begins in a linked list
- Swap list nodes in pairs
- Reverse a linked list in groups of a given size
- Intersection point in Y shaped linked lists
Enjoy learning, Enjoy algorithms!