This is a glossary of Machine Learning terms commonly used in the industry. We will add more terms related to machine learning, data science, and artificial intelligence in the coming future. Meanwhile, if you want to suggest adding more terms, please let us know through the message below.
Accuracy
Accuracy is used to evaluate any classification model. It is defined as the percentage of the total number of correct predictions. Mathematically it is represented as:
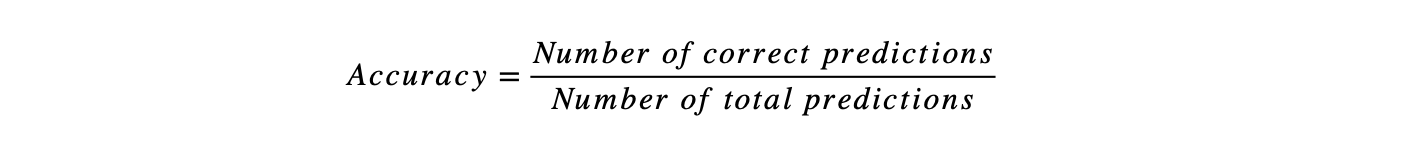
Algorithm
In Machine Learning, an algorithm is a procedure applied to the data to create a machine learning model. e.g., Linear Regression, Decision Trees.
Annotation
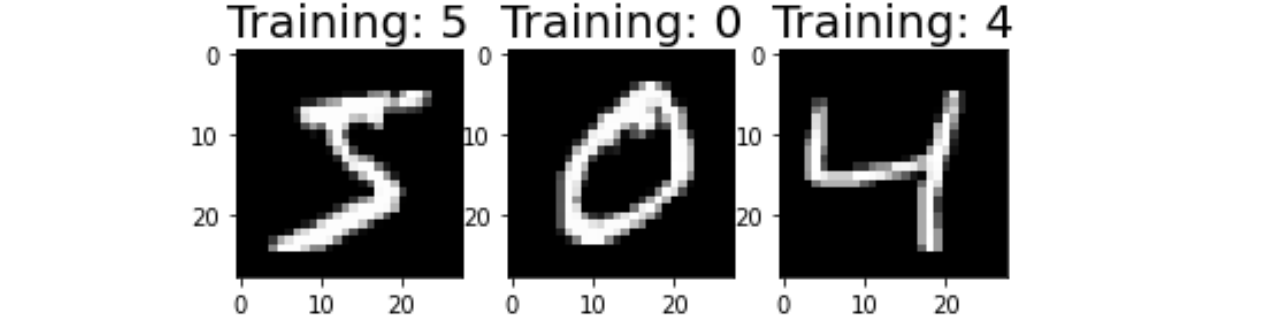
Process of assigning labels to the unlabeled data. For example, in the handwritten digit recognition task, if we assign a value of 8 to the image of 8.
Artificial Neural Networks
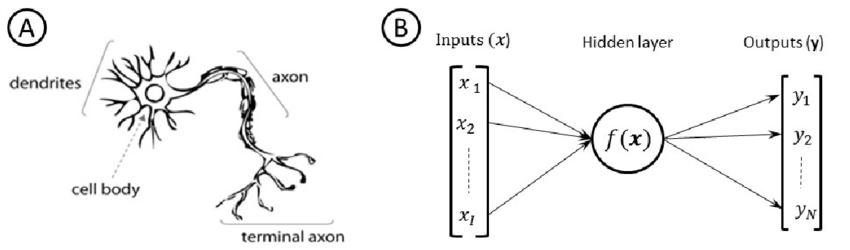
ANNs are Machine Learning algorithms inspired by biological neural networks that constitute animal brain cells.
Attribute
An aspect of an instance. If we talk about the structured data and store the values in a tabular format, the columns represent Attributes. For example, suppose we want to estimate today's atmospheric temperature, and for that, we recorded the atmospheric pressure, wind speed, and other essential properties. These properties are known as attributes.
AUC (Area Under Curve)
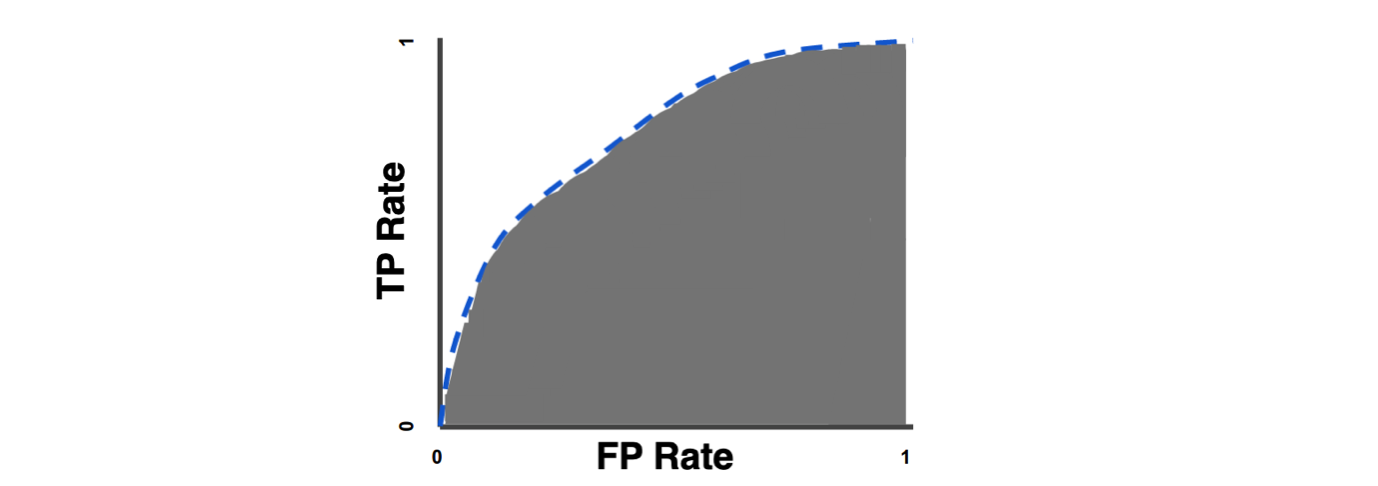
Area Under ROC Curve represents the classification model's aggregate performance for all classification thresholds. The ROC curve represents the variation in the true positive rate with respect to the false-positive rate.
Bias
Bias helps generalize the results by making our models less or more sensitive toward any feature or data point. Bias is considered a systematic error in the machine learning model due to incorrect ML process assumptions.
Bias Error
Error caused by algorithm's tendency to consistently learn the wrong thing by not taking all the data's information into account.
- High Bias:- Tendency of making assumptions about the data increases, and hence error increases.
- Low Bias:- Tendency of making assumptions about the data becomes lesser. Model Learns accurately on training data.
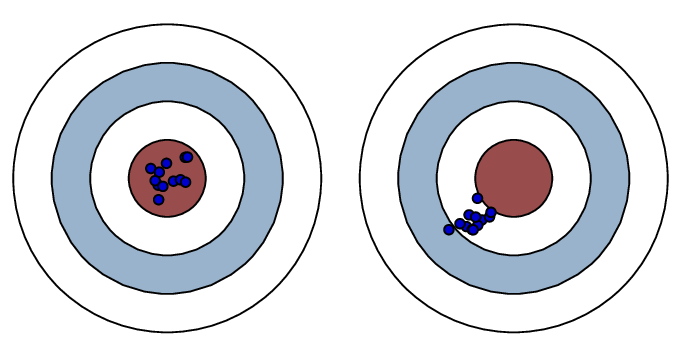
The right-side diagram below shows that points scatter all around the circle's center, hence having a lower bias.
But there is a high bias in the right diagram, as scatter happens only in a particular direction.
Low Bias vs. High Bias
Classification
Classification is a problem statement in Machine learning where models try to predict the output category. There can be two types of classification:
- Binary classification:- Classifies input in two binary classes; for example, an image contains a cat or not, Statement as True or False.
- Multi-label Classification:- Classifies objects in multiple classes. For example, the image simultaneously detects the presence of a House, Cat, Dog, etc.
Classification Threshold
It is the limiting value based on which a particular decision is made. Suppose a machine learning model predicts a cat's presence in any image with the surety of X%. We have set criteria that if confidence > 60%, then that will be a valid prediction. Then the threshold value is 60 for the classification.
Clustering
A type of unsupervised learning where the model groups the input data into different buckets based on some inherent data features. Generally, clusters consist of items having similar characteristics. The most commonly used clustering algorithms are K-Means, Hierarchical Clustering, and Affinity Clustering.
Confusion Matrix
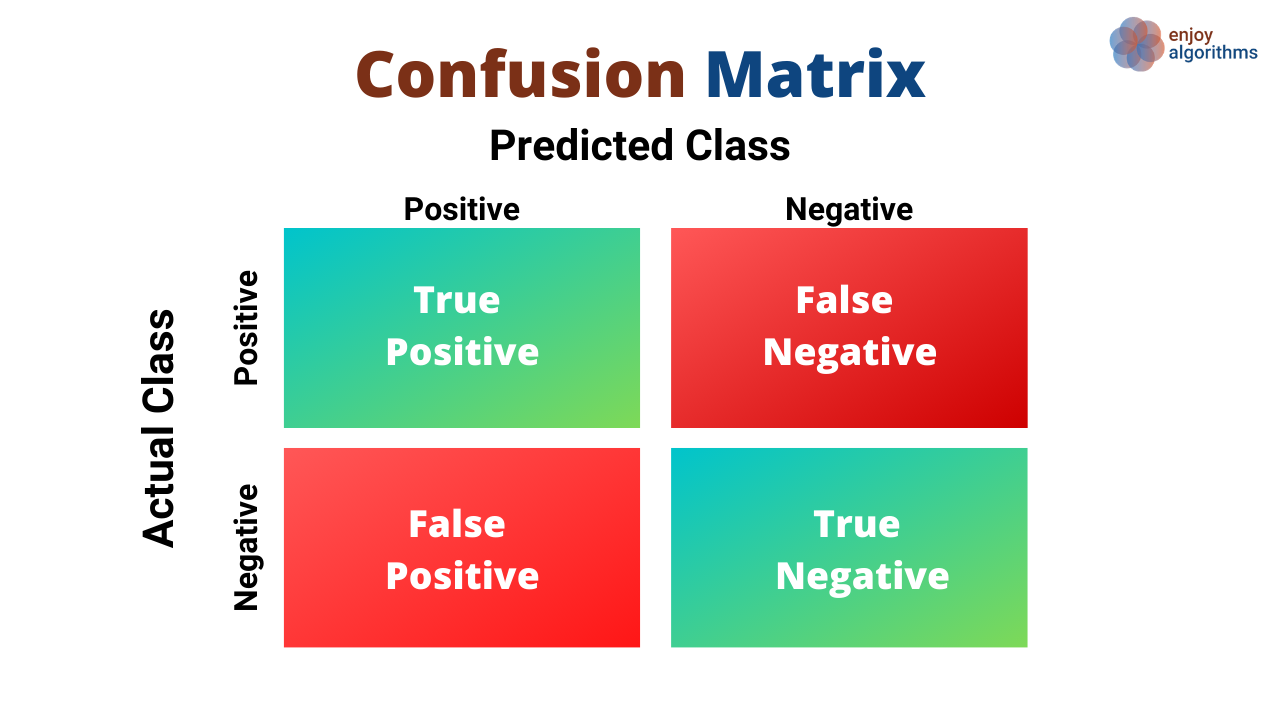
A metric for performance measurement of machine learning classification problem where output can be two or more classes. It groups the prediction into four categories,
- True Positive: Image of Cat classified as Image of Cat by the machine learning model.
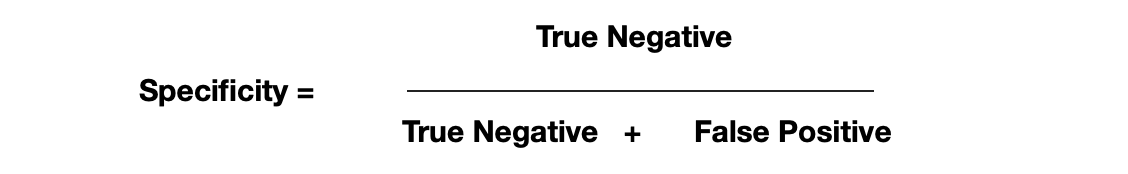
- True Negative: There was no cat in the Input Image, and the Machine learning model also predicted no cat.
- False Positive: Image of Dog is classified as Image of Cat by the ML model. This is also called Type I Errors.
- False Negative: There was a cat in the Input Image, but the Machine learning model predicted no cat. They are also called Type II Errors.
Convergence
A state during training a machine learning model when a change in the loss values becomes less between consecutive epochs. More specifically, if the change in the cost of the loss function is very minute, then it could be said that the model has found the minima, or its position will not change further, i.e., it has converged.
Deep Learning
A subfield of machine learning that deals with algorithms based on Artificial Neural Networks and is capable of understanding the temporal and spatial dependencies. It is also known as deep structured learning.
Dimension
Dimension in machine learning means the number of features that have been used as Inputs for the machine learning algorithms.
Dropout
A type of regulariser that is used to prevent over-fitting by dropping out hidden or visible units while training neural networks.
Epoch
1 Epoch = 1 iteration over the entire dataset.
Extrapolate
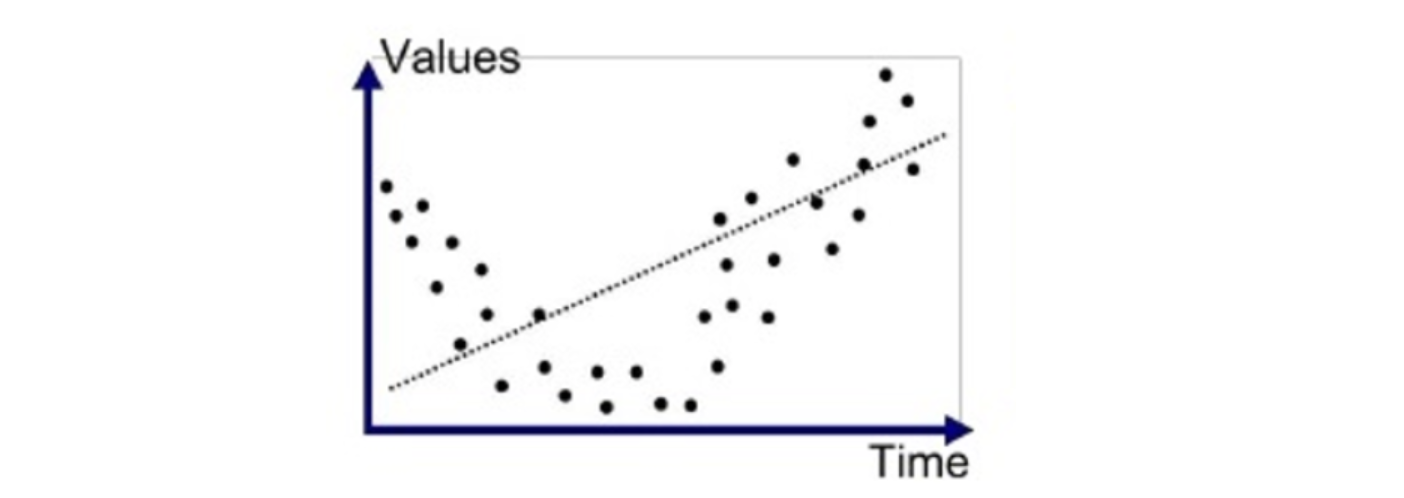
A type of estimation beyond the original observation range.
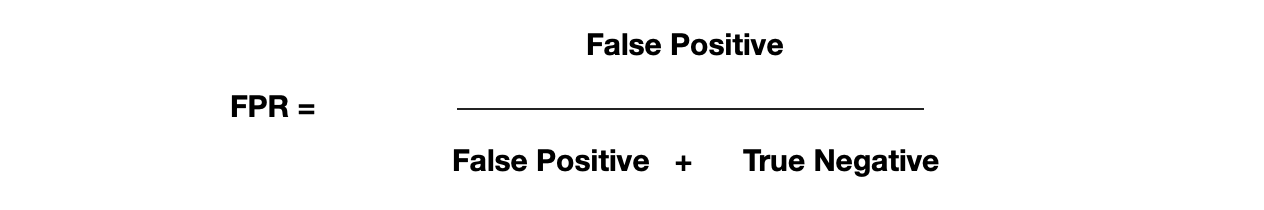
False Positive Rate (FPR)
Mathematically it is calculated as:
Feature
Features are known as attributes and values (finally used for training). Temperature is Attribute, and Temperature = 25°C is a feature.
Feature Vector
A feature vector lists all the features fed to the ML model.
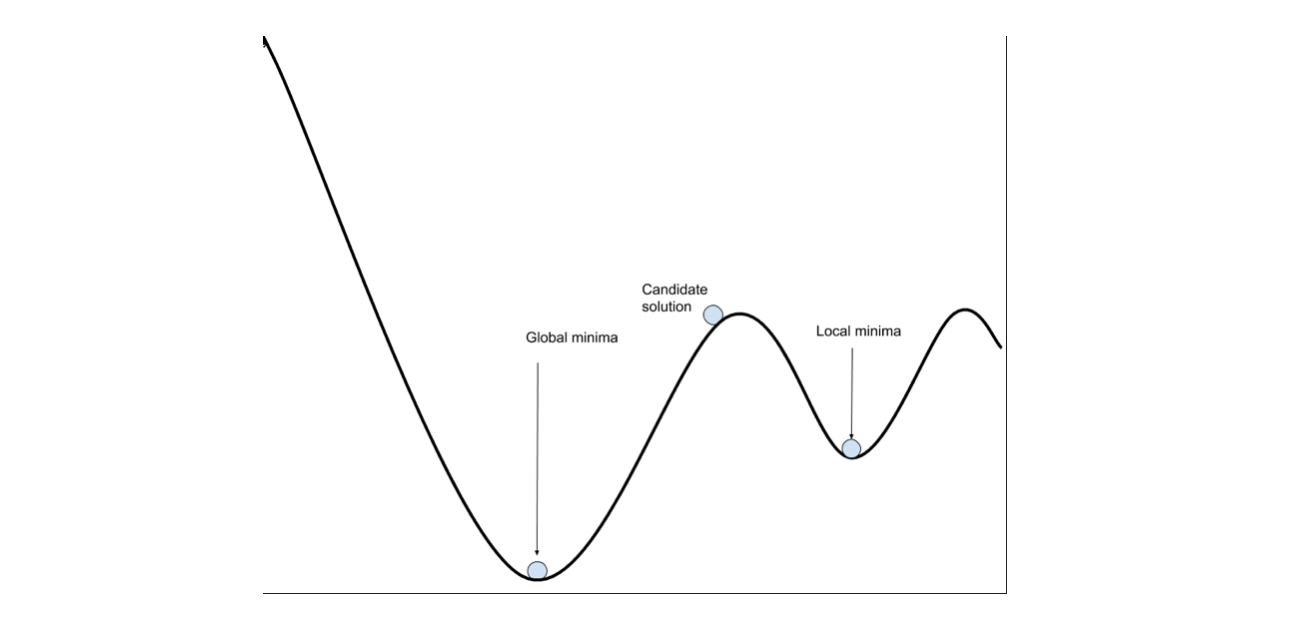
Global Minima
The loss function value reached a minimum globally over the entire loss function domain. It is the smallest overall value of a function over its entire range.
Hidden Layers
Layers in-between the Input and Output Layers in a neural network are hidden layers.
Hyperparameters
A parameter whose value is used to control the learning process. E.g., The number of hidden layers in a Neural Network.
Instance
A sample, row of feature values in the dataset. It is also called Observation.
i.i.d. sample
Itmeanseach random variable of the sample has the same probability distribution, and all are mutually independent.
Label
The output data is used in training a supervised learning model. e.g., To train a Cat Classifier Model, we need to prepare a dataset in which we label the image by saying whether it is a cat or not cat.
Learning Rate
A tuning parameter in any optimizing problem determines the step size at each epoch while moving towards any loss function's minima (Global / Local ).
Loss
In simple terms, Loss = (Actualvalue) - (Predictedvalue). It's the same as error; hence, the Lower the loss value, the better the model (Unless overfitted)
Local Minima
The value of the loss function becomes minimum at that point in a local region. It is a point where the function value is smaller than nearby but possibly greater than at a distant point.
Machine Learning
A computer science field that gives computers the ability to learn without being explicitly programmed.
Model
Model is the output of any ML algorithm run on the data. It is a data structure that stores weight and bias matrices containing the learned parameters.
Neural Networks
Machine Learning algorithms are inspired by biological neural networks, which constitute animal brain cells.
Normalization
Rescaling feature values to constrain dataset values to a standard range in any regression problem. It improves computation speed.
Noise
Additional meaningless information present in the data.
Null Accuracy
Accuracy can be achieved by directly predicting the most frequent class in any classification problem.
Observation
A sample, row of feature values in the dataset. It is also called an instance.
Optimizers
Methods that change the value of parameters so that losses reach the minimum. They are used to solve optimization problems by minimizing the cost function. E.g., Gradient Descent
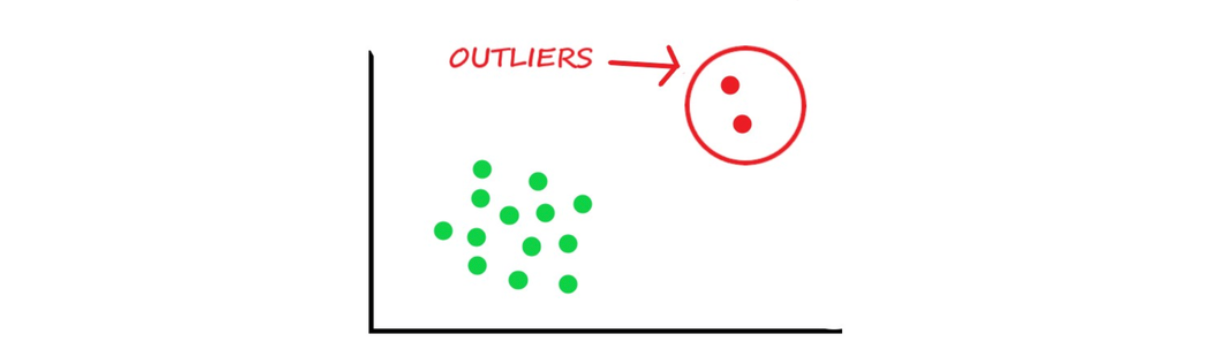
Outlier
Data Samples that differ significantly from other observations.
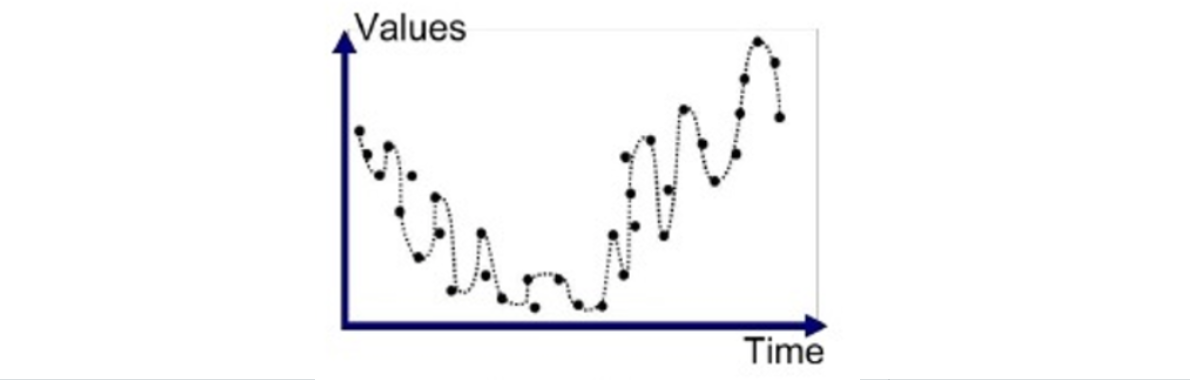
Overfitting
A situation when the model training error becomes significantly less than the model testing error. In this case, the model performs very well on training data but poorly on test data.
Parameters
Variables whose value we learn from training any machine learning model. e.g., Weights of neural networks.
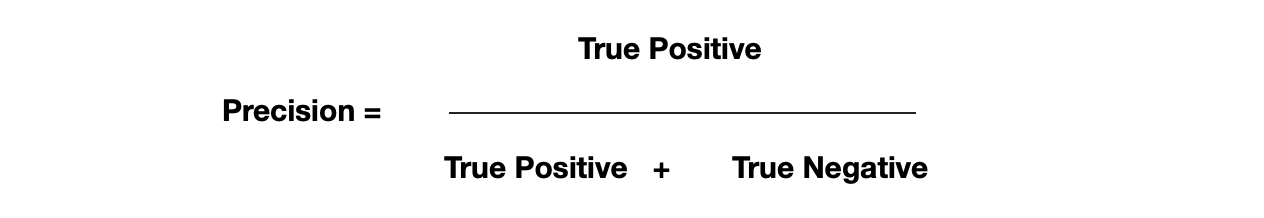
Precision
Precision tries to answer the question, What portion of True Positive is actually correct?
Recall
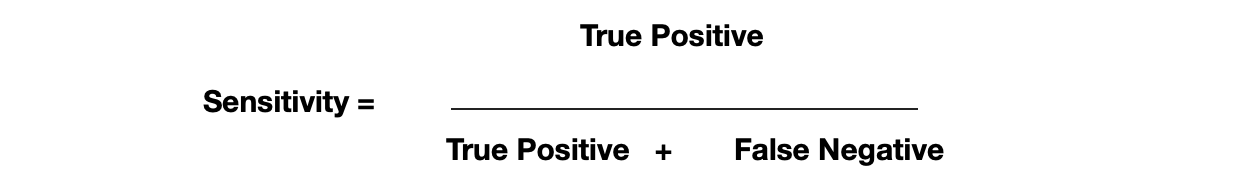
Recall tries to answer the question of, What portion of Positive is identified correctly?

Regression
A type of machine learning in which prediction output is continuous.
Regularization
A technique that is used to combat the problem of overfitting.
Reinforcement Learning
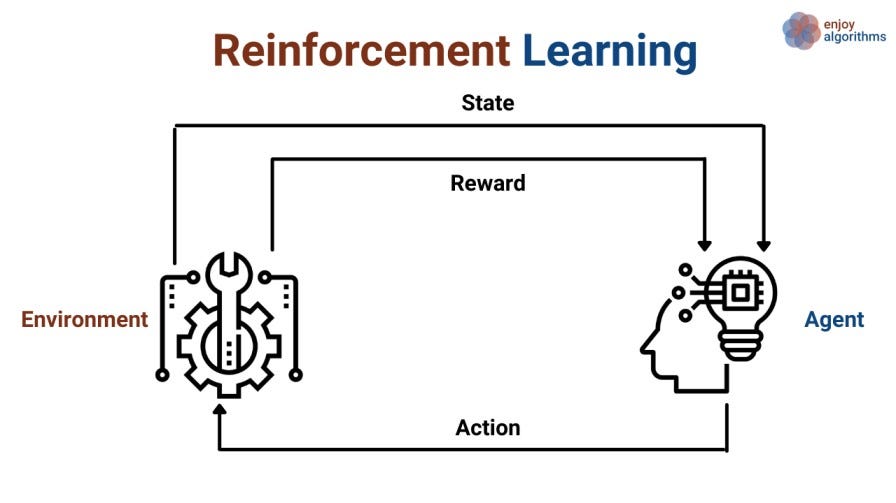
A subset of machine learning in which learning is based upon maximizing the reward based on the actions taken by the agents acting in an environment.
ROC (Receiver Operating Characteristic) Curve
A graph of True Positive Rate vs. False Positive Rate is used to check a classification model's performance at different classification thresholds.

Sensitivity
Specificity
Supervised Learning
Training a machine learning model under the supervision of a labeled dataset.
Test Set
Data samples are used to check the generalisability of the machine learning model. These sets are unseen to the model.
Train Set
Dataset used in training the machine learning model.
Transfer Learning
A method in which a machine learning algorithm picks the weights of already trained models and fine-tunes them as per the problem's requirements.
True Positive Rate
Same as Recall.
Type 1 Error
Same as False Positive
Type 2 Error
Same as False Negative
Underfitting
A situation in which the machine learning model does not learn the variation present in the data.
Universal Approximation Theorem
For ANN, if a Model is trained for the input range of (a,b), the model would be expected to perform well on the test data set, which lies within (a,b) only.
Unsupervised Learning
A class of machine learning in which training is based upon an unlabelled dataset. E.g., Dimensionality Reduction, Clustering.
Validation Set
A dataset that is used to validate the trained model while training by checking the generalisability of tuned parameters.
Variance
An error from sensitivity to small fluctuations in the training dataset. It can be of two types:
- Low variance:- Refers to the situation in which model output varies very little.
- High variance:- Refers to the situation in which the model starts following the noise patterns very accurately, and eventually, it overfits the data.
Predictions are hitting the bull's eye in the left diagram below while testing the model. Hence it has low variance. And in the right diagram, predictions are scattered and failed to converge while testing; hence it has high variance.
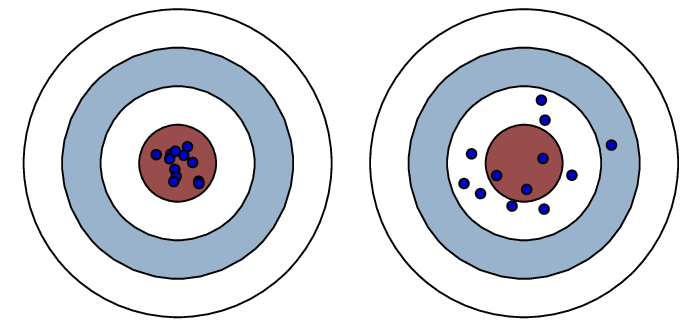
low Variance High Variance
Weights
A learnable parameter in machine learning.
Z-Mean
Standardization is also known as Z-mean normalization.
Additional Reference to Explore: https://developers.google.com/machine-learning/glossary